This product was not featured by Product Hunt yet. It will not be visible on their landing page and won't be ranked (cannot win product of the day regardless of upvotes).
LoomFlow: Open-Source Visual ETL
One open-source visual canvas for data pipelines & AI
One open-source visual platform for end-to-end data pipelines, AI native. One intuitive drag-and-drop canvas with zero friction. Launch production-ready data pipelines the same day you clone the repo.
Hey Product Hunt! 👋 I'm Harshad, maker of LoomFlow.
I’ve spent years building data systems and workflow automation, and ran into the exact same frustration over and over: you either wait around on single-core Python scripts and brittle glue code, or pay absurd enterprise licensing fees for legacy visual tools.
I wanted something different: One open-source workspace to blend data, automate pipelines, AI native. Run fast, local-first workflows right out of the box. Ship complete data workflows the same day you clone the repo.
So, I built LoomFlow.
It gives you the intuitive, drag-and-drop power of modern canvas tools backed by a high-performance, multi-threaded engine—benchmarking up to 57x faster than standard data pipelines.
What makes it tick:
⚡ Blistering Speed & Local-First: High-performance execution engine with sub-millisecond transforms and smart disk caching (freeze node outputs to Parquet on the fly).
🧠 AI-Native, Not AI-Bolted: Seamlessly drop LLM nodes, multimodal reasoning, and embeddings directly into your DAG without writing custom glue code.
🧩 Extensible by Design: Zero proprietary lock-in. Drop in your own custom nodes, connect new models or tools with simple Python handlers, and export full pipelines to declarative YAML for autonomous agents.
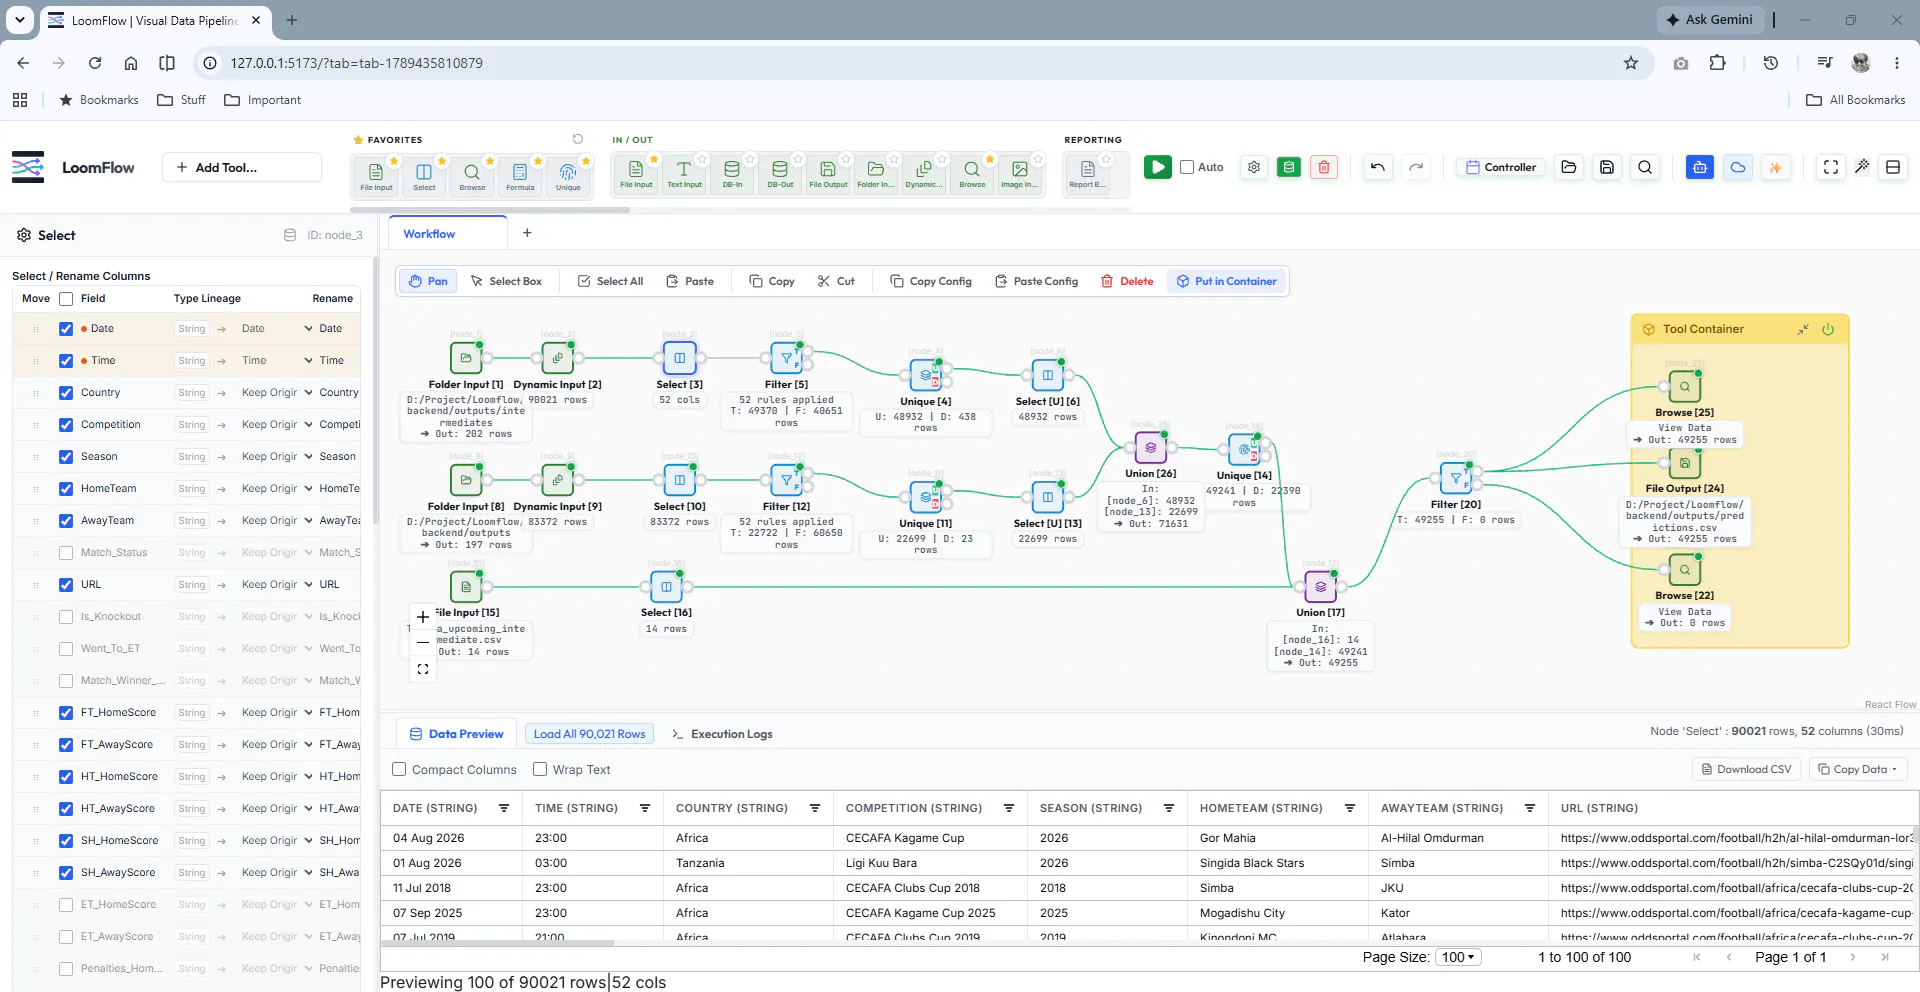
💻 Interactive Visual Canvas: Smooth node-based DAG workflow built to take you from raw data sources to live pipelines in minutes.
We are 100% open-source. Clone it, run it locally, break things, and tell me what you want to see next.
Check out the repo, drop a star if you dig the vision, and let me know in the comments: what’s the most painful part of your current data pipeline setup? 🚀
No comment highlights available yet. Please check back later!
About LoomFlow: Open-Source Visual ETL on Product Hunt
“One open-source visual canvas for data pipelines & AI”
LoomFlow: Open-Source Visual ETL was submitted on Product Hunt and earned 2 upvotes and 1 comments, placing #139 on the daily leaderboard. One open-source visual platform for end-to-end data pipelines, AI native. One intuitive drag-and-drop canvas with zero friction. Launch production-ready data pipelines the same day you clone the repo.
LoomFlow: Open-Source Visual ETL was featured in Open Source (68.9k followers), Artificial Intelligence (479.1k followers), GitHub (41.4k followers) and Data & Analytics (5.9k followers) on Product Hunt. Together, these topics include over 172.1k products, making this a competitive space to launch in.
Who hunted LoomFlow: Open-Source Visual ETL?
LoomFlow: Open-Source Visual ETL was hunted by Harshad Barge. A “hunter” on Product Hunt is the community member who submits a product to the platform — uploading the images, the link, and tagging the makers behind it. Hunters typically write the first comment explaining why a product is worth attention, and their followers are notified the moment they post. Around 79% of featured launches on Product Hunt are self-hunted by their makers, but a well-known hunter still acts as a signal of quality to the rest of the community. See the full all-time top hunters leaderboard to discover who is shaping the Product Hunt ecosystem.
Want to see how LoomFlow: Open-Source Visual ETL stacked up against nearby launches in real time? Check out the live launch dashboard for upvote speed charts, proximity comparisons, and more analytics.

 Harshad Barge
Hey Product Hunt! 👋 I'm Harshad, maker of LoomFlow.
I’ve spent years building data systems and workflow automation, and ran into the exact same frustration over and over: you either wait around on single-core Python scripts and brittle glue code, or pay absurd enterprise licensing fees for legacy visual tools.
I wanted something different: One open-source workspace to blend data, automate pipelines, AI native. Run fast, local-first workflows right out of the box. Ship complete data workflows the same day you clone the repo.
So, I built LoomFlow.
It gives you the intuitive, drag-and-drop power of modern canvas tools backed by a high-performance, multi-threaded engine—benchmarking up to 57x faster than standard data pipelines.
What makes it tick:
⚡ Blistering Speed & Local-First: High-performance execution engine with sub-millisecond transforms and smart disk caching (freeze node outputs to Parquet on the fly).
🧠 AI-Native, Not AI-Bolted: Seamlessly drop LLM nodes, multimodal reasoning, and embeddings directly into your DAG without writing custom glue code.
🧩 Extensible by Design: Zero proprietary lock-in. Drop in your own custom nodes, connect new models or tools with simple Python handlers, and export full pipelines to declarative YAML for autonomous agents.
💻 Interactive Visual Canvas: Smooth node-based DAG workflow built to take you from raw data sources to live pipelines in minutes.
We are 100% open-source. Clone it, run it locally, break things, and tell me what you want to see next.
Check out the repo, drop a star if you dig the vision, and let me know in the comments: what’s the most painful part of your current data pipeline setup? 🚀