Speech-to-speech model benchmarks on live phone calls
Cekura Bench publishes voice AI benchmarks you can verify. Our new speech-to-speech benchmark tests 9 realtime voice models, including GPT Realtime 2.1, Gemini Live, Grok and Phonic, as complete phone agents on live calls: 82 scenarios, three runs each. Models are ranked on reliability, data accuracy, stalled calls, response time and cost, and every call transcript is public. Cekura Bench also covers voice agent benchmarks and STT benchmarks, with TTS benchmarks coming soon.
Hi everyone, I am Sidhant from Cekura.
Today we are launching our speech-to-speech benchmark. We ran 9 realtime voice models as the full agent inside the same open-source Pipecat phone agent, with the same prompt, tools and phone line. Each model handled 82 scenarios across a clinic booking flow and a Medicare intake, three times each. A call passes only if the agent reaches the right outcome and saves every field correctly.
Results:
Most reliable: GPT Realtime 2.1, 79.3% of scenarios passed on all three runs
Fastest: Phonic v1, 1.60s median response
Lowest cost: GPT Realtime 2.1 Mini, $0.020 per minute
A cascade baseline (Flux, GPT-4.1, ElevenLabs Flash) scored 82.9%, above every realtime model
Every call links to its transcript, tool calls and scores, and the agent and test cases are on GitHub.
We would value your feedback, especially on which models we should add next.
About Cekura Bench on Product Hunt
“Speech-to-speech model benchmarks on live phone calls”
Cekura Bench launched on Product Hunt on October 8th, 2026 and earned 169 upvotes and 18 comments, placing #4 on the daily leaderboard. Cekura Bench publishes voice AI benchmarks you can verify. Our new speech-to-speech benchmark tests 9 realtime voice models, including GPT Realtime 2.1, Gemini Live, Grok and Phonic, as complete phone agents on live calls: 82 scenarios, three runs each. Models are ranked on reliability, data accuracy, stalled calls, response time and cost, and every call transcript is public. Cekura Bench also covers voice agent benchmarks and STT benchmarks, with TTS benchmarks coming soon.
On the analytics side, Cekura Bench competes within SaaS, Developer Tools and Artificial Intelligence — topics that collectively have 1M followers on Product Hunt. The dashboard above tracks how Cekura Bench performed against the three products that launched closest to it on the same day.
Who hunted Cekura Bench?
Cekura Bench was hunted by Garry Tan. A “hunter” on Product Hunt is the community member who submits a product to the platform — uploading the images, the link, and tagging the makers behind it. Hunters typically write the first comment explaining why a product is worth attention, and their followers are notified the moment they post. Around 79% of featured launches on Product Hunt are self-hunted by their makers, but a well-known hunter still acts as a signal of quality to the rest of the community. See the full all-time top hunters leaderboard to discover who is shaping the Product Hunt ecosystem.

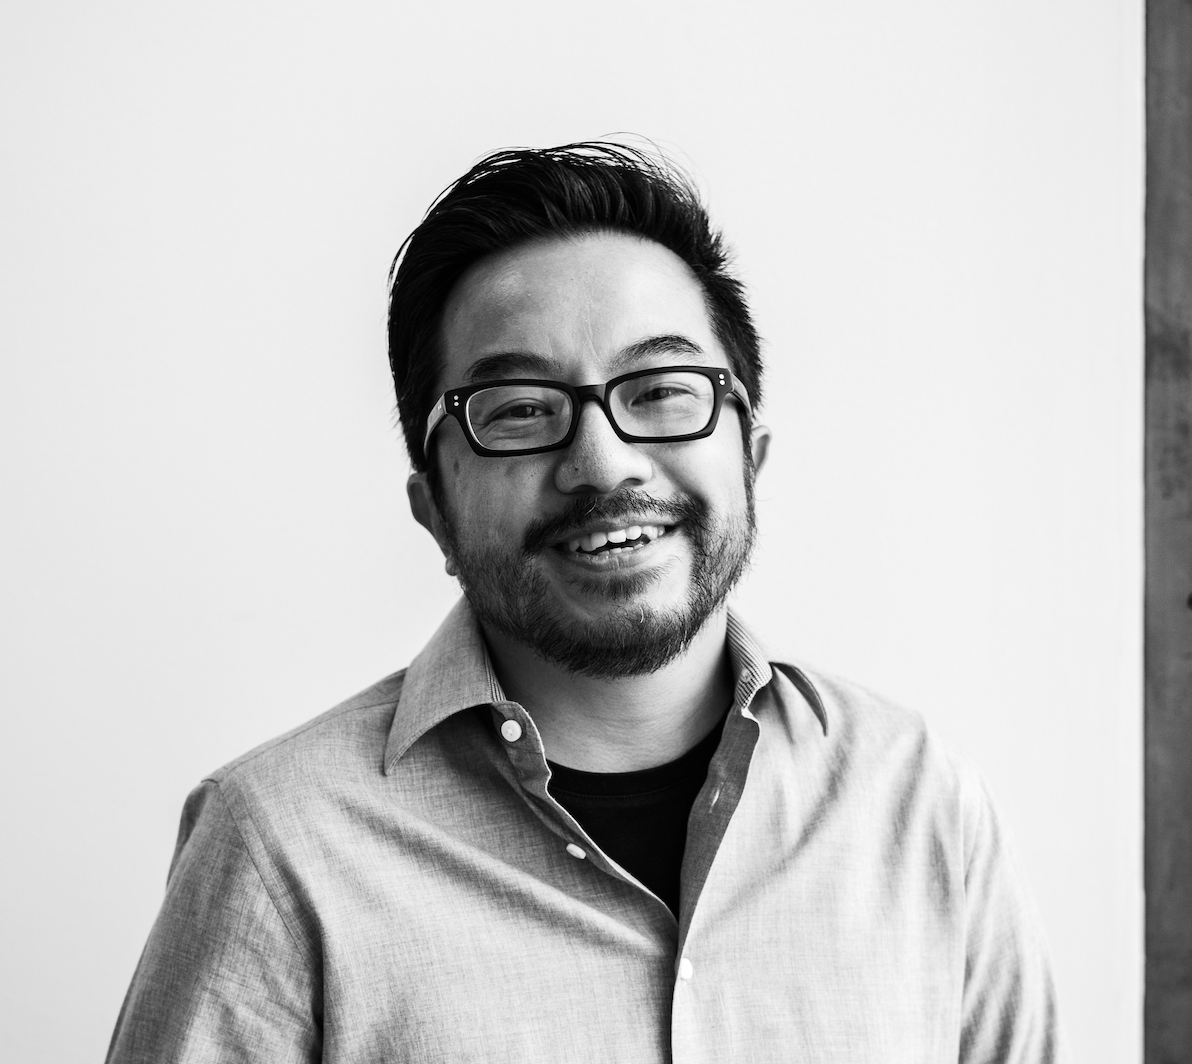 Garry Tan