This product was not featured by Product Hunt yet. It will not be visible on their landing page and won't be ranked (cannot win product of the day regardless of upvotes).
Product upvotes vs the next 3
Waiting for data. Loading
Product comments vs the next 3
Waiting for data. Loading
Product upvote speed vs the next 3
Waiting for data. Loading
Product upvotes and comments
Waiting for data. Loading
Product vs the next 3
Loading
ContextSlim: Token Reduction Toolkit
Compress 100k-char docs by 90% and boost AI accuracy by 200%
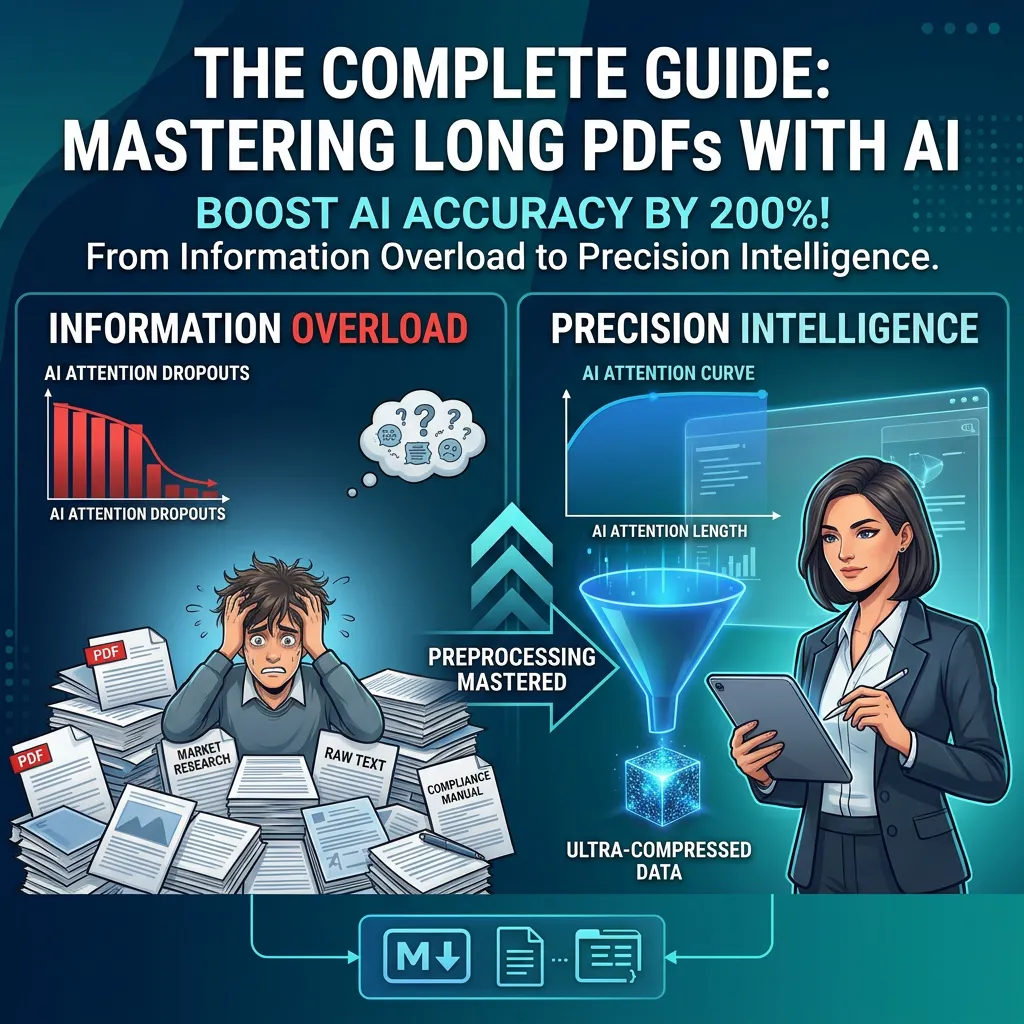
Stop wasting AI tokens on long doc noise. ContextSlim is an automated prompt & no-code workflow system designed to strip headers, footers, and fluff from huge PDFs before feeding them to Claude or GPT-4o. Prevent memory dropouts, eliminate hallucinations, and cut API costs. What's Inside: • 3-Filter Compression Framework (Clean, Structure, Compress) • Battle-tested System Prompts for zero-hallucination processing • Automated Make/Zapier workflow blueprints for hands-off batch runs
I’m Shirakam, creator of ContextSlim: Token Reduction Toolkit.
As an avid AI user, I hit a wall every time I fed 100k+ character PDFs into Claude or GPT-4o: constant memory dropouts, wild hallucinations, and wasted API tokens. Sound familiar?
The issue isn’t the AI—it's the token clutter (headers, footers, legal fluff, and raw text noise). Modern LLMs lose detail in the middle of long prompts.
That’s why I built ContextSlim.
It’s a complete system designed to:
Cut token noise by 90% using a 3-Filter Compression Framework.
Eliminate hallucinations by isolating key metrics & semantic logic.
Automate everything via hands-off Make/Zapier blueprints.
I’d love to hear your thoughts! What’s your biggest bottleneck when processing long documents with AI?
About ContextSlim: Token Reduction Toolkit on Product Hunt
“Compress 100k-char docs by 90% and boost AI accuracy by 200%”
ContextSlim: Token Reduction Toolkit was submitted on Product Hunt and earned 0 upvotes and 1 comments, placing #217 on the daily leaderboard. Stop wasting AI tokens on long doc noise. ContextSlim is an automated prompt & no-code workflow system designed to strip headers, footers, and fluff from huge PDFs before feeding them to Claude or GPT-4o. Prevent memory dropouts, eliminate hallucinations, and cut API costs. What's Inside: • 3-Filter Compression Framework (Clean, Structure, Compress) • Battle-tested System Prompts for zero-hallucination processing • Automated Make/Zapier workflow blueprints for hands-off batch runs
On the analytics side, ContextSlim: Token Reduction Toolkit competes within Productivity, Artificial Intelligence and No-Code — topics that collectively have 1.2M followers on Product Hunt. The dashboard above tracks how ContextSlim: Token Reduction Toolkit performed against the three products that launched closest to it on the same day.
Who hunted ContextSlim: Token Reduction Toolkit?
ContextSlim: Token Reduction Toolkit was hunted by Miko Shiraka. A “hunter” on Product Hunt is the community member who submits a product to the platform — uploading the images, the link, and tagging the makers behind it. Hunters typically write the first comment explaining why a product is worth attention, and their followers are notified the moment they post. Around 79% of featured launches on Product Hunt are self-hunted by their makers, but a well-known hunter still acts as a signal of quality to the rest of the community. See the full all-time top hunters leaderboard to discover who is shaping the Product Hunt ecosystem.
For a complete overview of ContextSlim: Token Reduction Toolkit including community comment highlights and product details, visit the product overview.

 Miko Shiraka
Hey Product Hunt community! 👋
I’m Shirakam, creator of ContextSlim: Token Reduction Toolkit.
As an avid AI user, I hit a wall every time I fed 100k+ character PDFs into Claude or GPT-4o: constant memory dropouts, wild hallucinations, and wasted API tokens. Sound familiar?
The issue isn’t the AI—it's the token clutter (headers, footers, legal fluff, and raw text noise). Modern LLMs lose detail in the middle of long prompts.
That’s why I built ContextSlim.
It’s a complete system designed to:
Cut token noise by 90% using a 3-Filter Compression Framework.
Eliminate hallucinations by isolating key metrics & semantic logic.
Automate everything via hands-off Make/Zapier blueprints.
I’d love to hear your thoughts! What’s your biggest bottleneck when processing long documents with AI?